
Every database has a way to auto-generate primary key values, but the mechanism — and its quirks — differ enough between dialects that a straight copy-paste migration often breaks. Understanding how sequences, identity columns, and auto-increment relate to each other is essential before you move a schema between PostgreSQL, MySQL, SQL Server, Oracle, or any of the other engines FoxSchema supports.
Three different mechanisms, one goal
All three approaches solve the same problem — generate a unique, increasing number for each new row — but they're implemented at different layers:
- Auto-increment (MySQL, MariaDB, SQLite) is a column attribute. The engine tracks the next value internally and increments it on insert. There's no separate database object to inspect or reuse elsewhere.
- Identity columns (SQL Server, Azure SQL, and modern PostgreSQL via
GENERATED AS IDENTITY) are also column-level, but under the hood they're usually backed by a hidden sequence-like generator you can seed and increment independently. - Sequences (PostgreSQL, Oracle, IBM Db2) are standalone schema objects, decoupled from any single column. You can pull the next value with
nextval('seq_name'), share one sequence across multiple tables, or reset it without touching the table definition at all.
Syntax across dialects
The same intent — "auto-generate this primary key" — looks different everywhere:
- MySQL / MariaDB:
id INT AUTO_INCREMENT PRIMARY KEY - SQLite:
id INTEGER PRIMARY KEY AUTOINCREMENT(in most cases the plainINTEGER PRIMARY KEYrowid alias is enough —AUTOINCREMENTonly matters if you need to guarantee IDs are never reused) - SQL Server / Azure SQL:
id INT IDENTITY(1,1) PRIMARY KEY - PostgreSQL (modern):
id INT GENERATED ALWAYS AS IDENTITY PRIMARY KEY, or the olderSERIALshorthand, which is really sugar for a column default tied to an auto-created sequence - Oracle: a named
SEQUENCEobject plus either a trigger or, since 12c,GENERATED AS IDENTITYon the column - IBM Db2:
GENERATED ALWAYS AS IDENTITY, conceptually close to SQL Server but built on Db2's own sequence machinery - ClickHouse: no native auto-increment at all — it's an analytical engine without traditional single-row primary key semantics, so IDs are typically generated application-side or derived from a hash
Where migrations go wrong
A few specific gotchas show up repeatedly when moving schemas between these dialects:
- Starting values and gaps. Sequences can skip numbers on rollback or crash by design — this is normal in PostgreSQL and Oracle but can surprise teams used to MySQL's tighter (though not guaranteed) behaviour.
- Shared sequences. If a source schema uses one Oracle sequence across several tables, a naive migration to MySQL — where auto-increment is always per-column — will silently fragment that shared numbering into independent counters.
- Resetting after a bulk load. After copying rows with explicit IDs, PostgreSQL and Oracle need an explicit
setval()orALTER SEQUENCE ... RESTARTto resync the sequence with the max existing ID — otherwise the next insert collides. - SERIAL vs IDENTITY in PostgreSQL itself. They behave almost identically, but only
IDENTITYis SQL-standard and prevents accidental manual inserts into the backing sequence — worth normalising on during any schema cleanup.
How FoxSchema handles the translation
This is exactly the kind of dialect-specific detail that comparing two schemas needs to get right rather than paper over. When FoxSchema diffs a source and target schema, its readiness panel flags auto-increment and identity differences as objects that translate but need a quick review, rather than silently generating SQL that either loses a shared-sequence relationship or produces a syntax error on the target dialect. For dialect pairs where the semantics genuinely diverge — like Oracle's sequence-plus-trigger pattern moving to MySQL's per-column auto-increment — the generated migration SQL follows the closest native equivalent on the target, and you review it before anything touches a live database.
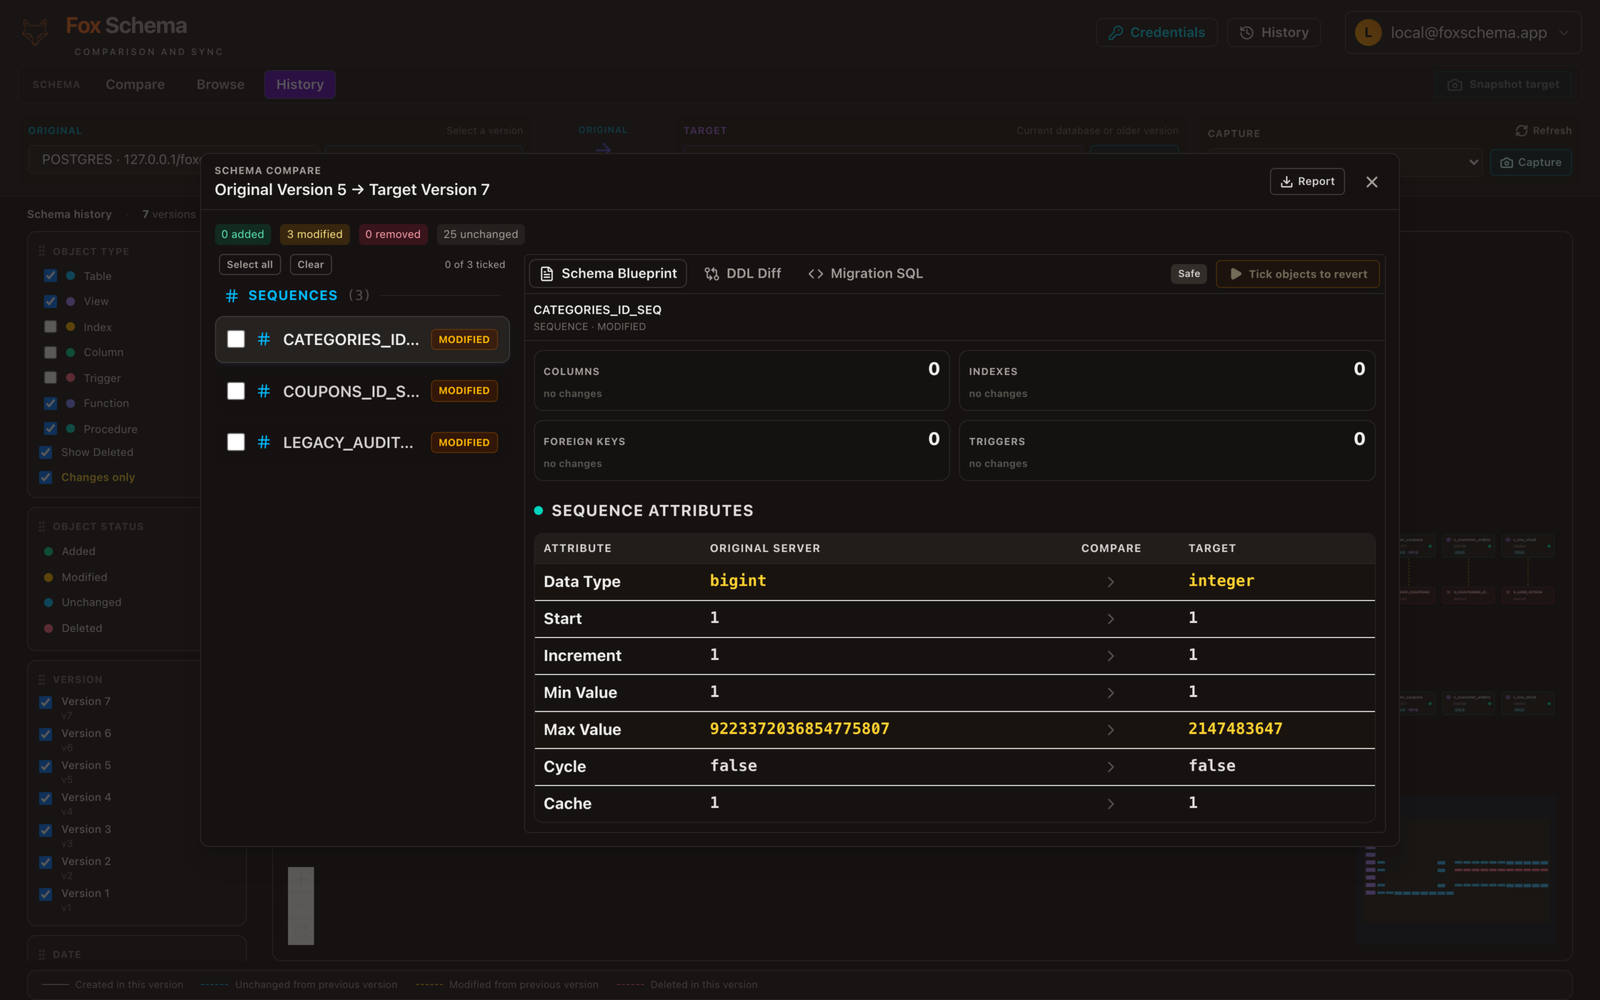
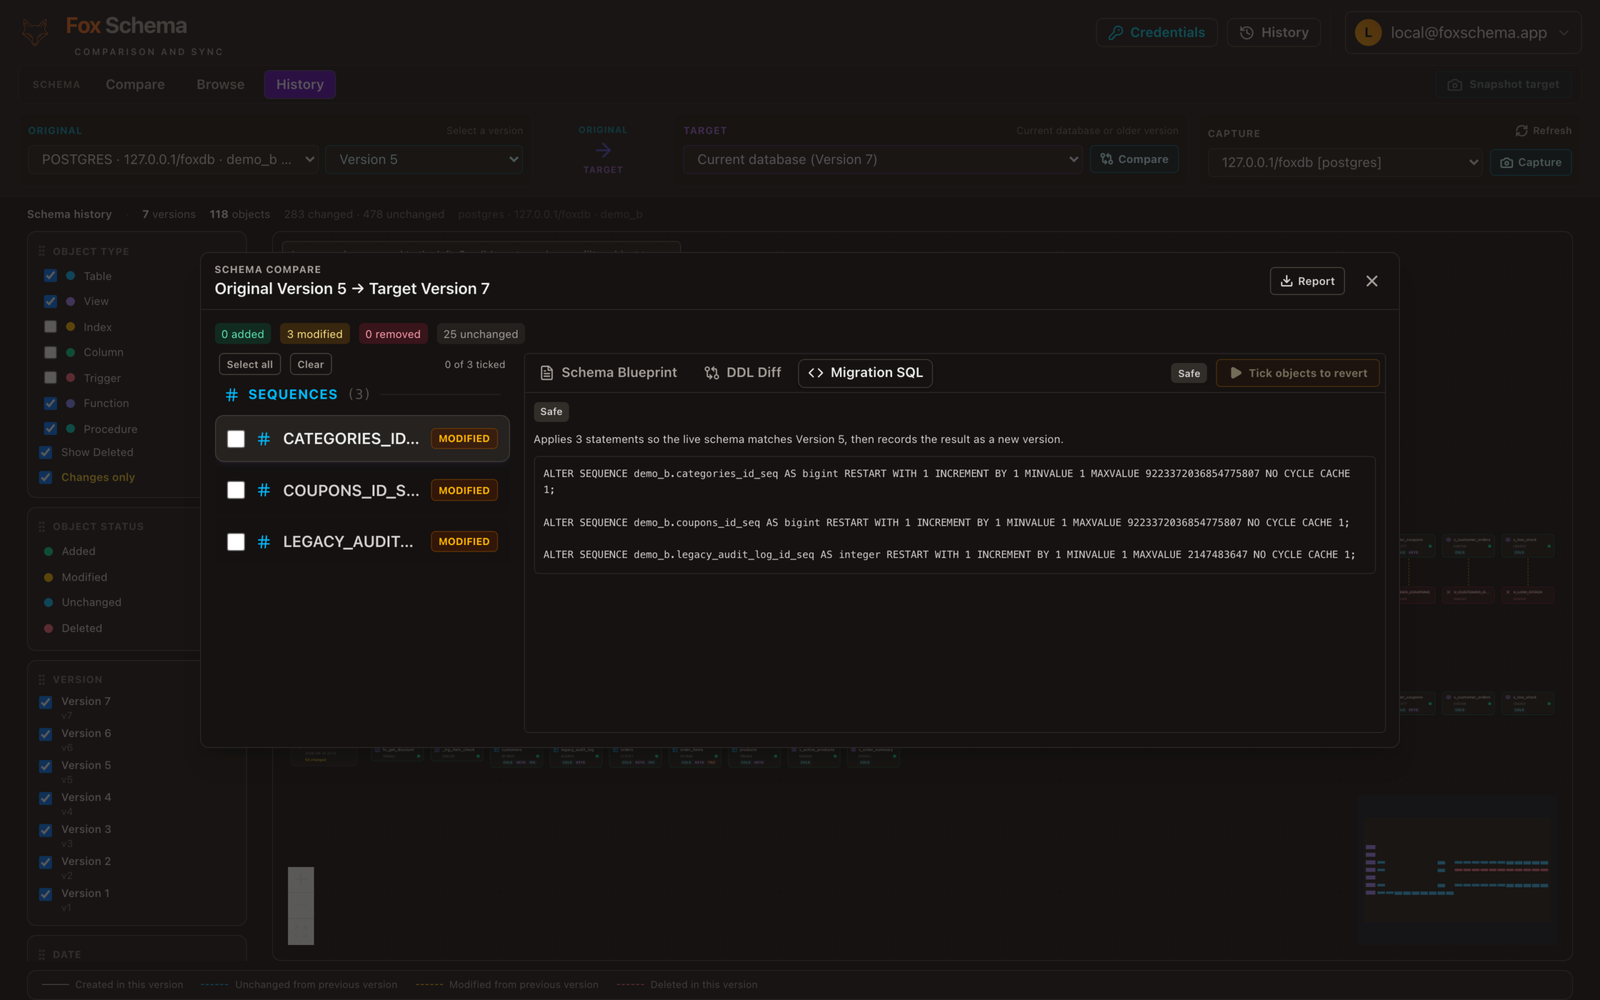
Try it yourself
If you're mid-migration and want to see exactly how your identity and sequence definitions map onto a different dialect, install the FoxSchema CLI or run the self-hosted web app locally and point a comparison at your two schemas — see the docs for connection setup. For related reading, see how we handle Oracle to PostgreSQL migrations, where the sequence-to-identity conversion shows up directly. Head to the install page to get started.
